The AI SDR Hallucination Problem (And How to Add a Fact-Audit Layer)
October 2, 2025 · 4 min read · by Ahmet Faruk Yilmaz, Founder of Asphia
TL;DR
AI SDRs invent prospect-specific claims, funding rounds, and job titles because language models generate plausible text rather than verified facts. A separate audit model should check every claim against the source data before the copy is approved.
AI SDRs do not hallucinate only on rare edge cases. They invent funding rounds, misquote job titles, and describe products a company does not sell. Language models generate statistically plausible text, not verified facts. A better prompt will not fix that. A separate audit pass must run before any email reaches a reviewer or sending queue.
Why the Problem Is Structural, Not Just a Prompting Issue
Cold email personalization asks the model to write something specific about a named person at a named company. When the source data contains only a LinkedIn URL, job title, and company domain, the model fills the gaps with training data. That data can be old, aggregated, and wrong. The result is a fluent claim with no factual basis.
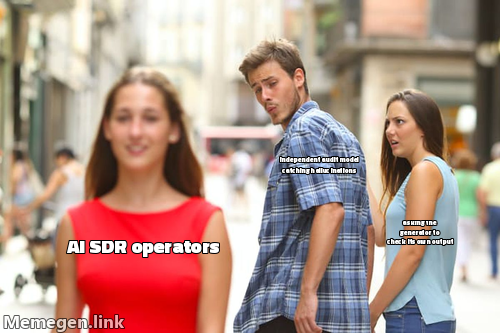 Self-review can miss errors. Verify material claims against sources and keep a human approval gate.
Common hallucination patterns in AI SDR copy:
- Inventing a funding round the company announced in the model’s training window but which is now stale or incorrect
- Attributing a product or feature to a company that belongs to a competitor
- Generating an “icebreaker” about a recent hire or promotion that never happened
- Quoting a company’s employee count from a range that is months out of date
The deeper risk is that self-review can miss errors. Asking the same model to “check your work” is not independent verification. A model may repeat a false belief during review, so self-reported confidence scores and unsourced_claims fields in structured output are signals, not audits. Verify material claims against source data and keep a human approval gate.
What an Independent Fact-Audit Layer Looks Like
The architecture has three components.
Source envelope. Every enrichment record passed to the generator becomes a signed source document. The audit model sees only what is inside that envelope. If the source does not support a claim in the generated email, the audit flags it even when it sounds true.
Separate model call with adversarial framing. The audit prompt treats the copy as a document that must prove every factual claim, not a draft to improve. Its instruction is direct: find claims about the prospect or company that the source data does not support. A different model provider adds genuine independence because its training weights, biases, and error patterns differ.
Human gate with diff visibility. Flagged emails go to a reviewer with each claim highlighted beside the relevant source record. The reviewer edits or rejects the email. The system does not ask the model that hallucinated to correct itself. Only an email with a clean audit result can enter the send queue.
We use this pattern at Asphia. Every lead goes through signal collection, enrichment, generation, an independent audit call, and human approval. The audit catches fabrications the generator misses in its own output.
The Temptation to Skip the Audit at Scale
When you generate hundreds of emails per day, the audit adds cost and latency. Skipping it or checking only ten percent can look efficient. It is not. Hallucinations cluster among prospects with thin source data, often the same group pushed hardest for personalization. A ten-percent sample can miss the leads most likely to produce fabricated claims.
The cost trade-off changes when you use a fast, inexpensive model for the audit step and reserve your highest-quality model for generation. Audit calls on a smaller, faster model are cheap enough to run on every lead. The math favors full coverage over sampling when you factor in the reputation cost of a hallucinated email reaching a real prospect.
Teams building done-with-you outbound systems or evaluating AI cold email setups should look for an audit layer. Vendor demos often omit it, but it becomes critical in production.
Signals That Your AI SDR Is Hallucinating
Tests often use well-known companies with plenty of training data, so hallucinations stay hidden. They tend to surface in production among:
- Smaller companies with sparse public profiles
- Non-English-speaking markets (models have less training data in local business contexts)
- Recently founded companies whose details postdate the model’s training cutoff
- Prospects whose job titles changed within the last year
To diagnose the problem, compare a batch of generated emails with the source records. Check every claim about a company or person against the enrichment data. If discrepancies appear in more than a small percentage of records, the system needs an audit layer.
Building Confidence Without Fabrication
The goal is grounded personalization, not detail at the cost of accuracy. A short icebreaker based on a confirmed signal, such as a recent job change, scraped product page, or job post, outperforms a long fabricated paragraph about funding history and team size.
Constrain the generator to the source envelope. The email can reference a confirmed signal. If the source contains only a domain and job title, the email should respect that limit. Sparse data should produce shorter, more conservative copy. That is correct behavior.
The audit layer enforces this constraint at inference time rather than relying on the generator to self-limit.
If you are evaluating AI outbound infrastructure, we can show you where a fact-audit layer fits in a managed outbound service stack.
Request the signal tier list.
A practical view of how we rank observable signals before outreach. We review each request for fit and may reply by email; delivery is not automatic.
By submitting, you agree to processing described in our Privacy Policy.
Your request was submitted. If it is a fit, we may follow up by email.
One more step: send the prepared request to [email protected]
FAQ
What is AI SDR hallucination?
AI SDR hallucination happens when a language model invents facts about a prospect or their company during copy generation. Examples include wrong job titles, fictional funding rounds, or products the company does not sell. The model generates text that sounds accurate but is not grounded in your actual source data.
Why can AI SDR workflows hallucinate during personalization?
Personalization pressure can amplify the problem. When a model is asked to write a highly specific, prospect-tailored opening line from sparse source data, it may fill knowledge gaps with plausible-sounding fabrications rather than admit uncertainty. Risk depends on the model, prompt, sources, and review controls; verify material claims before sending.
How does a fact-audit layer work in an AI outbound system?
A fact-audit layer runs a second, independent model call immediately after copy generation. It receives only the raw source data you provided, such as the enrichment record, LinkedIn snippet, and signal, plus the generated email. It can flag claims that cannot be traced to the source, but automated audits can miss errors; verify material claims and keep a human approval gate.
Can the same AI model audit its own output?
A separate review call may help identify errors, but model choice alone does not establish reliability. Treat generated copy as suspect, verify material claims against the source data, and keep a human approval gate before sending.
What happens to emails that fail the fact audit?
Flagged emails should not be silently discarded or auto-corrected. The right design surfaces the specific flagged claims to a human reviewer alongside the original source data, so the reviewer can edit or reject before the email enters the send queue. Auto-correction by the same model that hallucinated is unreliable.
Does a fact-audit layer slow down outbound at scale?
The audit adds one extra model call per lead. With a fast, lower-cost model handling the audit step and a higher-quality model handling generation, the combined latency stays manageable. At high volume, batch-parallel execution keeps throughput acceptable, but errors can remain and human verification is still required before sending.
Ahmet Faruk Yilmaz
Founder of Asphia. He builds and runs signal-based B2B outbound engines for lean teams, and writes about cold email, Clay, deliverability, and GTM engineering.
Want this run for you?
Get a free GTM analysis. We show you the exact engine we would build.
Request the planning framework →